How to Run an MSP Backup Restore Test That Proves Recovery
September 20, 2026 · 1358 words
Published by Steven Delaney
A successful backup job answers one question: did the backup process report completion? A restore test asks whether the MSP can retrieve the right data, rebuild what it depends on, and return a useful service to the client. Those are different outcomes.
Build each test around a named business service, an agreed recovery target, a safe destination, and evidence that the recovered service works. Start with a limited exercise, document what it proves, and expand coverage deliberately. A green report should describe an observed result, not an assumption about everything the client could recover.
Choose the service and failure scenario
Select a service whose interruption would matter to the client: shared project files, an ordering application, or a document workspace. Identify the people who use it and the task they need to resume.
Then state what has failed. Accidental deletion of a folder, loss of a server, and loss of access to an entire site require different recovery paths. A file restore cannot demonstrate that an application stack will recover after its hosting environment disappears.
Write one sentence describing the exercise. For example: "Recover the ordering application into an isolated environment from an available backup, then demonstrate that an authorized user can find an order and create a test record."
This is a hypothetical scenario, not a claim about a particular client's systems. Adapt it to the actual workload and explicitly list anything excluded, such as production cutover or recovery of a third-party integration.
Agree on what counts as recovered
Set acceptance criteria with the client before the test. The recovery time objective, or RTO, is the target time allowed to restore the defined service. The recovery point objective, or RPO, describes how far back the recovered data may be relative to the interruption.
Suppose an exercise assumes an interruption at noon and the latest usable recovery point is 11:15. That leaves a 45-minute gap. Whether the result is acceptable depends on the agreed objective and whether the application data actually represents that point in time.
Specify when the recovery clock starts and stops. Record preparation performed before timing begins. A test that preloads data or provisions replacement infrastructure can measure part of recovery, but its duration should not be presented as the full interruption-to-service time.
Define the usable outcome too. "Server boots" may be a technical milestone; "an authorized user completes the agreed task with the expected records and permissions" is stronger service evidence.
Build a small test record
Create one record containing the information a second engineer would need to repeat the exercise:
- Scope: Client, business service, protected resources, and simulated failure.
- Recovery source: Backup identifier, recovery point, location, and required retention window.
- Dependencies: Identity, networking, keys, licenses, application configuration, and vendor assistance.
- Destination: Approved test environment, access restrictions, and isolation controls.
- People: Test operator, technical reviewer, client validator, and escalation contact.
- Acceptance: Timing boundaries, data checks, business task, and cleanup evidence.
Check these details against the service baseline captured during MSP client onboarding. Newly added databases, workspaces, or integrations may not be covered by the original backup selection.
Confirm recovery access is usable. A recovery procedure stored only on the system being restored, or a required key accessible only through an unavailable service, creates a dependency the exercise needs to expose.
Prepare a destination that cannot disrupt production
Treat the restored copy as a working system with real capabilities. It may contain scheduled jobs, email settings, integration credentials, or agents that reconnect automatically. Simply giving it a different machine name does not establish isolation.
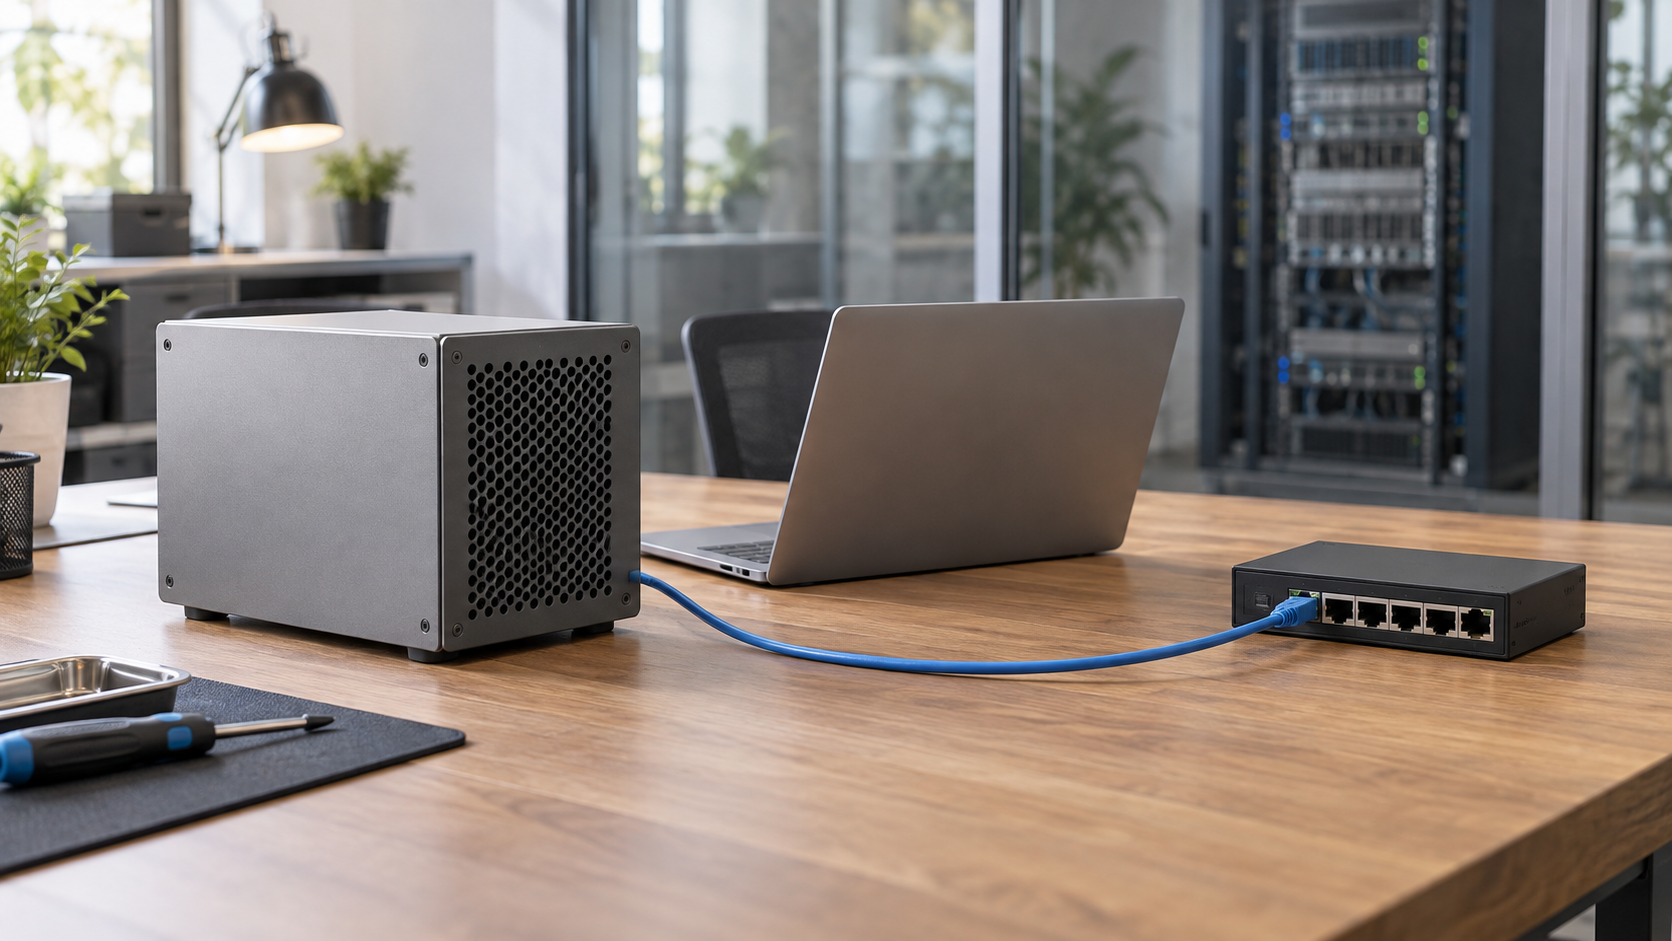
Before startup, verify the network and identity boundaries. Block unintended access to production and outbound services, use approved test endpoints where needed, and prevent the copy from sending customer messages, processing payments, or synchronizing changes back into live systems.
Protect restored client data with appropriate access controls. Keep different clients' recovery environments separate. Define who can inspect the data, how long the copy may remain, and who confirms its removal.
Use the MSP change management process for approvals, the test window, stop conditions, and any required production-side changes. Set resource limits so the exercise cannot silently consume storage or cloud capacity without an owner noticing.
Restore from the documented procedure
Ask a qualified engineer to follow the runbook, preferably someone who did not write it. Record every missing instruction, unavailable permission, unexpected prompt, and manual workaround. An expert quietly fixing gaps makes the test look easier than the next recovery will be.
Capture the selected recovery point before starting. Restore into the approved destination, follow the workload's supported recovery sequence, and collect job identifiers, errors, timestamps, and significant decisions. Check dependencies rather than assuming they arrived with the data.
Keep backup protection running during the exercise. Do not delete recovery points or relax retention controls to simplify testing. If a test unexpectedly touches production, stop under the agreed procedure and assess the impact before continuing.
A routine restore exercise does not establish that a backup is safe after a compromise. Suspected cyber incidents require their own investigation, clean recovery decisions, and validation before restored systems reconnect.
Validate the data and the business task
Separate technical restoration from application validation. A completed restore job is one piece of evidence. It does not establish that the right records, relationships, permissions, and supporting services are usable.
Choose checks appropriate to the workload. For files, open representative items and inspect expected versions and access permissions. For an application, use its supported consistency checks, inspect known records, and test the agreed workflow. Record the sample chosen and the limits of that sample.
Have the client validator confirm the business result in the isolated environment. In the ordering example, this might mean finding a known order and creating a clearly identified test record, with external fulfilment and notifications disabled. Verify both allowed access and a relevant denied-access case.
If a supplier integration cannot be exercised safely, mark it untested. Do not convert "not checked" into "passed" because the rest of the application works. The final result should distinguish completed checks, failures, and exclusions.
Compare the result with the promise
Report total observed recovery time alongside the agreed timing boundary. Break out delays such as obtaining approval, retrieving data, rebuilding dependencies, restoring the workload, and validating service. This shows which part needs attention.
Compare the actual usable data point with the RPO. A recent job timestamp is insufficient if the application data inside that backup is older or incomplete. Record how the data point was established and any uncertainty.
Use a simple outcome: passed within the defined scope, failed an acceptance criterion, or incomplete because a required check could not run. Include limitations even when the test passes. One successful workload test should not become a claim that every client system is recoverable.
Close gaps, clean up, and schedule coverage
Give each failure or missing dependency an owner, a due date, and a retest condition. "Update recovery documentation" is vague; "add the missing identity recovery steps and have another engineer repeat the exercise" has an observable finish line.
Use the action-tracking approach from an MSP post-incident review when several teams need to resolve a gap. Keep the original failed result and attach the retest evidence rather than rewriting the record as if the problem never existed.
Remove temporary systems, restored datasets, test accounts, and temporary access when the approved retention period ends. Verify cleanup and check that normal backup jobs remain healthy. Preserve the test evidence in its approved location without retaining unnecessary copies of client data.
Choose the next test based on business importance, system changes, previous failures, and service commitments. Rotate through workloads and recovery points instead of repeatedly testing the easiest folder. A useful recovery program leaves the MSP able to say exactly what was recovered, what worked, what remains uncertain, and who is addressing it.
Steven Delaney
MSP Industry Expert • Houston, TX
Strategic insights and practical guidance for the modern Managed Service Provider. Based in Houston, TX.